Managing network policy across a hybrid cloud setup often feels like trying to keep a dozen plates spinning at once. You have on-premise servers with strict rules, a public cloud instance that needs different access controls, and a handful of SaaS tools that everyone uses. The old method of manually updating ACLs on each proxy server just does not scale. If you are an IT security engineer or a cloud architect, you already know that manual updates are slow, error prone, and a direct path to a policy gap.
Automating proxy server policy enforcement across hybrid cloud environments removes human error, cuts deployment time from hours to minutes, and ensures consistent security rules whether traffic hits your data center or a public cloud instance. This guide walks through a practical automation framework using central policy management, CI/CD pipelines, and real-time monitoring to keep your network secure in 2026.
Why Manual Policy Enforcement Fails in Hybrid Clouds
A hybrid cloud environment is not just two locations. It is often a dozen or more. Your corporate headquarters might run a private cloud, your development team uses AWS, your data analytics team prefers Azure, and your sales team relies on a SaaS platform. Each of these environments has its own proxy server or gateway.
When you enforce policies by hand, you create drift. A rule gets updated in the data center but forgotten in the cloud instance. A developer adds a new microservice and forgets to update the egress proxy rules. Over time, your security posture becomes a patchwork of old and new rules. This is exactly how data leaks happen.
Automation solves the drift problem. It treats your proxy server policy as code. You write the rules once, store them in a central repository, and push them to every environment automatically.
The Core of Hybrid Cloud Policy Enforcement Automation
To automate successfully, you need three things working together.
- A central policy repository (think Git or a dedicated configuration management database).
- An automation layer that pushes policies to each proxy server or cloud gateway.
- A validation loop that checks whether the policy was applied correctly and alerts you if something failed.
Let us look at each piece.
Central policy repository
Store every rule in a version controlled system. This gives you an audit trail. You can see who changed what and when. If a rule breaks something, you can roll back instantly. Treat your proxy rules like you treat application code. Write them in a structured format such as YAML or JSON.
Automation layer
This is where the actual enforcement happens. Use a configuration management tool like Ansible, SaltStack, or Terraform to push the policy from the repository to each proxy server. For cloud native environments, you can use provider specific tools like AWS CloudFormation or Azure Policy. The key is that the push is triggered automatically whenever a change is committed to the repository.
Validation loop
After a policy is pushed, the system must verify it took effect. Run a set of automated tests. For example, try to reach a blocked domain from each environment. If the test fails, the system should roll back the change and notify the team. This prevents a bad rule from causing a widespread outage.
A Step-by-Step Process for Automation
Here is a numbered process you can adapt for your own infrastructure.
-
Audit your current proxy landscape. List every proxy server and cloud gateway in your hybrid environment. Note the vendor, the version, and the current policy set. This inventory becomes your source of truth.
-
Define a single policy schema. Choose a format for your rules. Stick with one schema across all environments. If you have different proxy vendors, write a translation layer that converts your schema into the vendor specific format.
-
Set up a Git repository for policies. Create a dedicated repo. Give it a clear structure. One folder for each environment, one folder for shared global rules. Protect the main branch with pull request reviews.
-
Write your automation scripts. Use your preferred configuration management tool. The script should pull the latest policy from the repo, apply it to the target proxy server, and report the result. Store the scripts in the same repo as the policies.
-
Configure a CI/CD pipeline. Use GitHub Actions, GitLab CI, or Jenkins. The pipeline triggers on every merge to the main branch. It runs the automation script against a staging environment first. If the staging tests pass, it promotes the change to production.
-
Build health checks. For each environment, create a set of synthetic transactions that test specific rules. A health check for a blocked category. A health check for an allowed domain. Run these checks every five minutes after a deployment.
-
Set up alerting. Connect your validation loop to your monitoring system. If a check fails, send an alert to PagerDuty, Slack, or email. Include the rollback command in the alert so an engineer can fix it fast.
Common Techniques and Mistakes
The table below outlines techniques that work well and mistakes that cause trouble.
| Technique | Why It Works | Common Mistake | Why It Hurts |
|---|---|---|---|
| Store policies in Git | Full audit trail, easy rollback | Storing policies in local config files | No version history, hard to recover |
| Use a CI/CD pipeline for deployment | Consistent, repeatable pushes | Manually SSH into each proxy server | Human error, missed updates |
| Validate with synthetic transactions | Catches misconfigurations fast | Relying only on proxy logs | Logs can be delayed or incomplete |
| Write vendor agnostic schemas | Works across hybrid environments | Hard coding vendor specific syntax | Breaks when you add a new cloud provider |
| Automate rollback on failure | Prevents extended outages | No rollback mechanism | A bad rule stays live for hours |
Expert Advice for the Automation Pipeline
“The most common failure point in automated policy enforcement is the validation step. Teams spend weeks building a beautiful pipeline but skip the part where the system proves the policy is working. Without validation, you are just automating your mistakes faster.”
* Senior Network Architect at a Fortune 500 retail company
This rings true in practice. A team at a financial services firm automated their proxy policy pushes but did not add validation. A typo in a CIDR block rule took down access to their payment processor for 45 minutes. The automation worked perfectly. It just automated the wrong rule. Add validation before you trust the pipeline.
Tools and Approaches to Consider
You have options when building your automation stack. Here is a bulleted list of approaches that work well in 2026.
- Ansible for pushing policies to on-premise proxy servers. It is agentless and works over SSH.
- Terraform for managing cloud native gateways like AWS Elastic Load Balancing or Azure Application Gateway.
- Custom Python scripts for translating your central policy schema into vendor specific formats like Squid ACLs or Nginx configs.
- GitHub Actions for the CI/CD pipeline. It integrates directly with your policy repository.
- Prometheus + Grafana for monitoring the validation health checks over time.
- Open Policy Agent (OPA) for writing fine grained, structured rules that can be evaluated at the proxy level.
For a deeper look at keeping your proxy servers healthy, read our guide on optimizing proxy server performance for enterprise networks. It covers tuning your proxy infrastructure so that automation does not introduce latency.
How to Handle Edge Cases in a Hybrid Environment
Hybrid clouds are messy by nature. You will run into situations that your standard automation flow does not cover.
Latency differences. A policy push to an on-premise proxy might take two seconds. A push to a cloud instance in a different region might take thirty seconds. Your pipeline needs to wait for confirmation from each target before declaring success. Set a reasonable timeout and handle timeouts as failures.
Vendor specific features. Some proxy vendors support advanced features like SSL inspection or content filtering that others do not. Your central schema should mark these as optional. If a target proxy cannot apply a rule, it should skip it and log a warning. Do not let a missing feature block the entire deployment.
Rollback complexity. If you push a bad rule to ten environments, you need to roll back all ten. Store the previous known good state in your repository. Your rollback script should apply that state to every target, not just the one that triggered the alert.
Regulatory compliance. If you work in healthcare or finance, some rules are mandated by law. Mark these rules as immutable in your schema. The automation pipeline should never allow a pull request to remove or modify a compliance rule without a special approval gate.
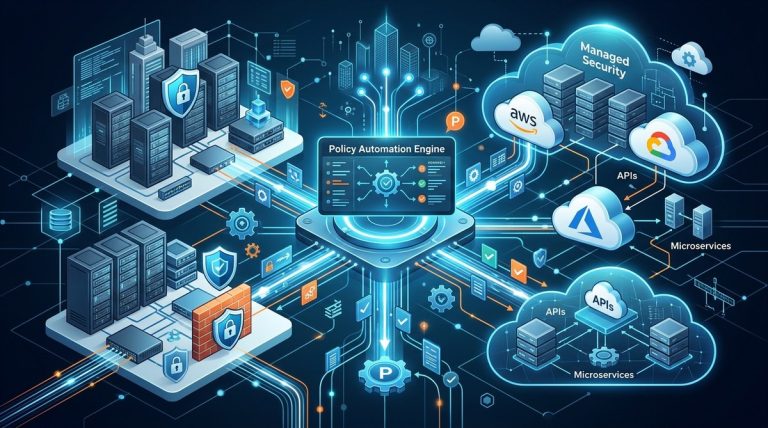
The Architecture of a Unified Policy System
Think of your policy system as a hub and spoke model. The hub is your Git repository. The spokes are the automation scripts and targets.
- The hub holds the canonical rules.
- Each spoke pulls the rules, translates them if needed, applies them, and reports back.
- A central dashboard collects the reports and shows the enforcement status of every environment.
This architecture makes it easy to add a new environment. Spin up a new proxy server, add a new folder in the repository, point the spoke at the new target, and the automation takes over.
What Happens When You Skip the Pre-Deployment Test
Skipping the test environment is a common shortcut. Teams think, “It is just a proxy rule change. It cannot break anything.” But it can.
Consider a rule that blocks traffic to a specific IP range. If you mistype the subnet mask, you could block a critical API endpoint. If you skip the staging test, that block hits production immediately. Your users start getting errors. Your support team gets flooded with tickets.
Always test in a staging environment that mirrors production as closely as possible. If you cannot afford a full staging environment, at least run a dry run that simulates the rule application without actually enforcing it.
For more on securing your proxy infrastructure, take a look at the ultimate guide to securing proxy servers against modern threats. It covers the baseline security measures that every automated policy should enforce.
Building a Culture of Policy as Code
Automation is not just a technical change. It is a cultural one. Your team needs to treat proxy policies with the same rigor as application code.
- Require code reviews for every policy change.
- Write unit tests for your policy translation layer.
- Document the schema and the automation flow in your team wiki.
- Run a postmortem after every failed deployment.
When your team treats policy as code, you get fewer mistakes and faster recovery times. The automation becomes a force multiplier instead of a source of new problems.
Moving from Reactive to Proactive Enforcement
With manual enforcement, you are always reacting. A user reports a blocked site. A security scan finds an open egress. You fix the rule and move on.
With automation, you become proactive. You can schedule policy audits that run automatically. You can compare the enforced policy against the desired policy and flag differences. You can even build a self healing loop that reverts unauthorized changes.
This shift from reactive to proactive is the real benefit of hybrid cloud policy enforcement automation. It frees you from the daily grind of manual updates and lets you focus on architecture and strategy.
Tying It All Together for Your Team
Hybrid cloud policy enforcement automation is not a one time project. It is an ongoing practice. Start small. Pick one proxy server and one environment. Build the automation for that single target. Validate it. Then expand to the next target.
Each time you add a new environment, you reinforce the process. You learn what breaks and how to fix it. Over time, you build a system that handles the complexity of your hybrid cloud without requiring constant human attention.
If you are still using manual methods, the risk is real. A single missed update can expose your network to data exfiltration or a compliance violation. The time to automate is now, while your environment is still manageable.
For a practical next step, read our guide on how to automate proxy server failover for high availability. It builds on the same automation principles and applies them to keeping your proxy infrastructure running during outages.
Your First Automation Sprint
Start this week. Do not wait for a perfect plan. Here is what you can do in one afternoon.
- Create a new Git repository for your proxy policies.
- Export the current rules from your main on-premise proxy server.
- Commit those rules to the repository.
- Write a simple script that copies the rules from the repo to a test proxy server.
- Run the script and verify the rules were applied.
That is your first automation loop. It is basic, but it works. From there, you add validation, CI/CD, and more targets. The hardest part is starting, and you just did.
Automation turns a chaotic hybrid cloud into a manageable, secure environment. Your team sleeps better. Your network stays consistent. And you spend less time fixing rules and more time building the next thing.