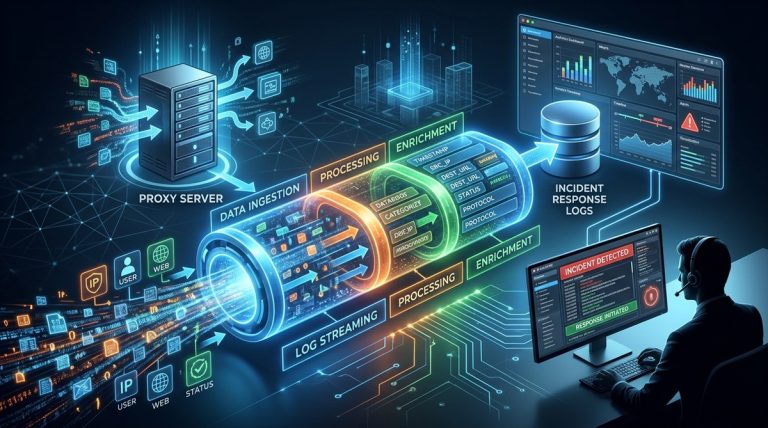
When your SOC phone rings at 3 AM with a possible data exfiltration alert, the first place you look is the proxy logs. You need to see which internal host talked to which external IP, at what time, and how much data moved. But if those logs are scattered across flat files with no structured pipeline, you waste precious minutes just finding the data. In 2026, threat actors move faster than ever. Your proxy server logging setup needs to match that speed.
A dedicated logging pipeline transforms raw proxy server data into actionable incident response intelligence. Instead of grepping through terabytes of text files, your team gets structured, searchable, and real-time log streams that feed directly into your SIEM, SOAR, and threat hunting platforms. This cuts mean time to detect from hours to seconds and gives your analysts the context they need to contain threats before they spread.
What a Dedicated Logging Pipeline Actually Does
A logging pipeline is not just “turning on logging” in your proxy config. It is an end to end system that collects, parses, normalizes, enriches, and forwards log events to your analysis tools. Think of it as a refinery. Raw proxy logs come in as messy text. The pipeline cleans them, adds context like geolocation and threat intelligence, and sends them where your team can use them.
Without this pipeline, your proxy server logging becomes a bottleneck. You might get logs, but they arrive late, lack critical fields, or get dropped under high traffic. A dedicated pipeline guarantees that every request and response is captured, structured, and available within seconds.
Why Your Proxy Server Logs Are Unique
Proxy logs are different from firewall logs or system logs. They contain application layer data. They show you the full URL, the user agent, the HTTP method, the response size, and sometimes even the POST body. This richness makes them incredibly valuable for incident response, but it also makes them harder to handle.
Consider a typical malware callback. A firewall log might show a connection to port 443 at an IP address. A proxy log shows the full HTTPS handshake, the SNI field, the requested path, and the response headers. That extra detail can mean the difference between a false positive and a confirmed compromise.
Building the Pipeline: A Step by Step Process
Here is how to set up a dedicated logging pipeline for your proxy infrastructure. Follow these steps in order.
-
Standardize your log format. Make sure every proxy server in your fleet outputs logs in the same schema. Use W3C extended log format or JSON. Avoid mixing formats between different vendors or versions. Consistency is the foundation of automation.
-
Choose a transport protocol. Do not write logs to disk and batch upload them. Use syslog over TCP with TLS, or use a message queue like Kafka or RabbitMQ. Your pipeline needs to handle bursts of traffic without dropping events.
-
Parse and normalize at ingestion. Use a log shipper like Logstash, Fluentd, or Vector. Strip out noise, rename fields to a common schema, and add timestamps in UTC. If your proxy logs use local time, convert them immediately.
-
Enrich with context. Add geolocation data for external IPs, match domains against threat intelligence feeds, and tag internal IPs with asset inventory information. This enrichment makes your SIEM queries much more powerful.
-
Forward to your analysis platform. Send the enriched logs to your SIEM, your data lake, and your threat hunting platform. Use separate streams for real time alerting and long term storage. Do not mix them.
-
Monitor pipeline health. Set up alerts for log volume drops, parsing errors, and queue backlogs. A silent pipeline failure can blind your entire SOC. Check it every shift.
Common Pipeline Mistakes and How to Fix Them
Even experienced teams make errors when designing their proxy server logging pipeline. The table below shows the most frequent mistakes and their solutions.
| Mistake | Why It Hurts Incident Response | The Fix |
|---|---|---|
| Logging to local disk only | After a compromise, attackers wipe logs. You lose everything. | Stream logs off box immediately using syslog or Kafka. |
| No timestamp normalization | Analysts waste time converting time zones during an incident. | Force all timestamps to UTC at the ingestion layer. |
| Dropping fields to save storage | You lose the user agent or response size, which are critical for threat hunting. | Store full logs in a cheap data lake. Only truncate for real time alerts. |
| Ignoring TLS metadata | Without SNI or certificate info, you cannot identify encrypted threats. | Enable SSL inspection logging or at least log the SNI field. |
| Single point of failure | One log shipper goes down, and your entire pipeline stops. | Run redundant shippers with load balancing and automatic failover. |
What to Look For in Your Proxy Logs
When you are hunting for threats, certain patterns stand out. Here are the signals your team should scan for in the proxy logs.
- Repeated connections to newly registered domains. Attackers often use domains that are only a few days old.
- Large data transfers to unusual destinations. Look for outbound traffic to cloud storage providers or countries where your company does no business.
- User agent strings that do not match your corporate browser policy. Automated malware often uses generic or outdated user agents.
- Authentication failures followed by success. This pattern suggests credential stuffing or brute force attacks.
- Connections to IP addresses on known blocklists. Enrich your pipeline with real time threat intelligence feeds.
“The proxy log is the single richest source of truth for understanding what users and devices are doing on your network. If you are not treating it as a first class data stream, you are flying blind during incident response.”
Senior SOC Manager, Fortune 500 financial services firm
How to Test Your Pipeline Before a Real Incident
You would not deploy a firewall without testing the rules. The same logic applies to your logging pipeline. Run regular drills to confirm that logs are flowing, parsing correctly, and reaching your SIEM within an acceptable latency window.
Try this test. Generate a controlled traffic pattern from a known internal host. Hit a test domain you control. Then check your SIEM. Can you find that event within 30 seconds? Does it include the correct source IP, destination domain, and user agent? If not, your pipeline has gaps.
Document the expected latency and field completeness for each log source. Share that with your SOC team so they know what to trust during an investigation.
Integrating Your Pipeline with Other Security Tools
Your proxy server logging pipeline should not live in isolation. It feeds into your broader security architecture. Connect it to your SOAR platform for automated response. For example, if the pipeline detects a host making outbound connections to a known C2 server, the SOAR can automatically block that host at the firewall and isolate it from the network.
Also feed your pipeline data into your threat hunting platform. Tools like Splunk, Elastic, or Chronicle can ingest structured proxy logs and run behavioral analytics. This is where you find the slow, low level attacks that traditional signatures miss.
For more on hardening your proxy infrastructure, check out this guide on securing proxy servers against modern threats. It covers the complementary controls that make your logging pipeline more effective.
The Cost of Not Having a Dedicated Pipeline
Let us talk about what happens when you skip this work. You get an alert from your EDR about a suspicious process. You check the proxy logs, but they are stored on the compromised server itself. The attacker already deleted them. You check the central log server, but it only has summary data, not the full request details. You cannot confirm the scope of the breach.
That is the reality for teams that treat proxy server logging as an afterthought. The cost is not just the incident response delay. It is the uncertainty. You never know if you caught everything.
A dedicated pipeline removes that uncertainty. It gives you a tamper resistant, searchable, and complete record of every outbound connection. That record is your best evidence during a post incident review and, if needed, during legal proceedings.
Choosing the Right Tools for 2026
The tooling landscape for log pipelines has matured. You have options. For open source, you can build with Vector, Kafka, and ClickHouse. For commercial, platforms like Cribl, Datadog, and Splunk offer turnkey solutions. The key is not which tool you pick. It is that you design the pipeline with incident response in mind.
Prioritize low latency delivery over batch processing. Prioritize field preservation over storage savings. Prioritize schema consistency over flexibility. These trade offs will serve you well when the next incident hits.
Putting It All Together for Your Team
You do not need to rebuild everything at once. Start with one proxy server. Set up the pipeline. Validate it. Then roll it out to your entire fleet. Document your schema, your enrichment rules, and your expected latency. Share that documentation with your SOC analysts so they know exactly how to query the data.
A dedicated logging pipeline turns your proxy infrastructure from a passive observer into an active defense tool. It makes your team faster, more accurate, and more confident during incidents. That confidence is priceless when you are the one on the call at 3 AM.
For a deeper look at how to optimize your overall proxy performance while maintaining security, read about optimizing proxy server performance for enterprise networks. And if you want to understand the full value of your proxy data, this article on why your proxy server logs are a goldmine for network security analytics will give you more ideas.
Your Next Steps Start Today
Pick one proxy server in your environment. Set up a test pipeline that streams its logs to a central collector. Run a traffic test. See how long it takes for the log to appear. Then show your SOC team the result. Once they see the speed and completeness of a dedicated pipeline, they will never want to go back.
Start small. Prove the concept. Then scale. That is how you build a proxy server logging system that actually supports your incident response goals.